Somebody on your team is about to put a number in a slide. The number will be 0.82, it will be labelled "answer quality", and everyone in the room will read it as "82% of our answers are good". That is not what it says, and the gap between what it says and what the room hears is the problem this post is about. A judge score looks like a measurement because it has two decimal places, and it gets treated like one because nobody in the room wrote the rubric. The people who did write the rubric know how far the number moved the last time they changed a word in it.
A judge score is the output of a model that was asked a question about another model's output. It inherits every property of a model answer: it is a sample from a distribution, it moves when you change the prompt, and it is confident whether or not it is right. What makes it useful is not that it is objective. It is that it is consistent, and consistency is what lets you compare Tuesday to Thursday. The rest of this post covers what the number actually measures, why it only compares to itself, how to calibrate it against human labels in one afternoon, how to pick a threshold you can defend, and the three biases that move the score when nothing about your product has changed.
What the number measures
An LLM judge is a model given three things: a rubric you wrote, the input a user sent, and the output your AI system produced. Sometimes it also gets a reference answer to compare against. It returns a verdict per row, which might be pass or fail, a number from 1 to 5, or a label from a short list. The score you see for a run is the mean of those per-row verdicts, normalised to sit between 0 and 1. So 0.82 on a binary rubric means 82 of 100 rows were judged pass. On a 1 to 5 rubric it means the average verdict sat a little above 4, which could be every row scoring 4, or half scoring 5 and half scoring 3, and the mean cannot tell you which.
That is the first thing to hold onto: the run score is a summary of verdicts, and the verdicts are the real data. A mean of 0.82 with all the failures concentrated in one intent (say, refund questions) is a different product from a mean of 0.82 with failures scattered evenly, and it calls for a different fix. Whenever you look at a run score, you should be able to click through to the rows behind it. If your tooling only stores the mean, you have thrown away the part of the result you can act on.
The second thing to hold onto is that the verdict is an answer to the rubric's question, not to the question "is this good". Here is a rubric of the kind we use for a support assistant, cut down to its core:
You are grading a customer support answer.

Question from the customer:
{input}

Answer from the assistant:
{output}

Return PASS if all of the following hold, otherwise return FAIL:
1. The answer addresses the customer's actual question.
2. Every factual claim is supported by the provided policy excerpt.
3. The answer does not promise anything the policy excerpt does not allow.

Give one sentence of reasoning, then the verdict on its own line.
Read that rubric and you can see what 0.82 means for this judge: 82% of rows satisfied all three conditions as the judge read them. It says nothing about tone, nothing about whether the customer's problem was actually solved, and nothing about the 18% beyond that they failed at least one line. Label the score "answer quality" and the room hears a broader claim than the rubric ever made. Label it "policy-grounded, on-topic, no over-promising" and the room hears roughly what it is.
Why scores only compare within one judge
Change a word in the rubric and the number moves, without anything about your product changing. Swap "every factual claim is supported" for "the main claims are supported" and a judge that was failing rows for one unsupported detail will start passing them. Swap the judge model for a newer version and the same rubric will be read a little differently, because the model reading it has changed. This is not a defect to be engineered away, it is the nature of the instrument. A thermometer calibrated in Fahrenheit does not report the same figure as one in Celsius, and neither is lying.
What follows from that is a rule worth writing on the wall:
A judge score is only comparable to another score from the same judge, the same rubric, and the same model.
Every dashboard that violates this rule eventually produces a meeting about a regression that never happened. The typical version goes like this. Someone tightens the rubric on a Wednesday because it was passing answers that should have failed. The score drops from 0.82 to 0.74. The line on the dashboard goes down, an alert fires, and by Thursday morning three people are looking for the deploy that broke answer quality. Nothing broke. The instrument changed, and the dashboard drew a line through two readings from different instruments.
The practical fix is to treat the judge as a versioned artifact with three parts: the rubric text, the judge model identifier, and the dataset the score was computed on. Change any one of the three and you have a new judge, which means you rerun your baseline with it before you compare anything. In EvaliQA a test plan pins all three, so a score always carries the version it came from, and a change to the rubric produces a new series on the chart rather than a step in the old one. If your setup does not do this, a text file listing the rubric version next to each dated score is enough to stop the Thursday meeting.
The same rule applies to numbers you read elsewhere. A judge score from a paper, a vendor's benchmark, or another team's dashboard was produced with a rubric and model you do not have, and it does not compare to yours. The only way to know whether your 0.82 is good is to know what your judge agrees with, which is what calibration measures.
How to calibrate a judge
Calibration is one afternoon of work and it is the difference between a metric and a decoration. The point of it is not to make the score higher. It is to find out how often the judge's verdict matches a person's verdict on the same row, so that when the score moves you know whether to believe it. The procedure is short enough that there is no reason to skip it, and the steps go in this order:
Label 50 rows by hand. Not 500. Fifty is enough to find gross disagreement, and small enough that a person will actually do it. Pick rows that span your traffic rather than the easy ones, and have the person label against the rubric text, not against their general sense of quality.
Run the judge over the same 50. Keep the raw verdicts and the judge's reasoning line, not the mean. The mean is what you are trying to understand; the rows are how you understand it.
Build the confusion matrix. A confusion matrix is a two-by-two count: rows the judge passed that the human passed, rows both failed, rows the judge passed that the human failed (a false pass), and rows the judge failed that the human passed (a false fail). Where does the judge pass what you failed, and fail what you passed?
Read the ten worst disagreements. Every time we have done this, the rubric was ambiguous rather than the judge being stupid. The next section is about what you find.
Fix the rubric and repeat once. Two rounds is usually enough. A third round usually means the rubric is trying to cover two different questions and should be split into two judges.
The two off-diagonal cells of the matrix matter differently depending on what the score is for. If the judge gates a release, a false pass is the expensive cell: it is a bad answer the gate let through. If the judge is used to triage rows for a person to review, a false fail is the expensive cell: it is wasted review time. Suppose your 50 rows come back with 4 false passes and 2 false fails. That is 6 disagreements in 50, and it tells you the judge is somewhat too lenient, which is the wrong direction for a release gate and a tolerable direction for triage.
The output of this is not a better score. It is a sentence you can say out loud: "when this judge says fail, it agrees with a human nine times in ten." That sentence is what makes the number usable in a release decision, because it turns a 0.82 into a claim with a known error rate. Without it, the number is a model's opinion with decimal places, and the room is right to be suspicious of it.
How to read the disagreements
Sort the 50 rows by how far the judge and the human disagreed, and read the top ten with the rubric open beside you. What you are looking for is the line in the rubric that the two readers interpreted differently. In the support rubric above, condition 2 says every factual claim must be supported by the policy excerpt. A human labeller reading a row where the assistant said "refunds usually arrive within five days" will fail it if the excerpt says nothing about timing. A judge might pass it, reasoning that "usually" is a hedge rather than a claim. Neither reading is wrong. The rubric did not say what to do with hedged claims, so each reader decided for themselves.
The fix is a rubric line that removes the choice. Condition 2 becomes: "Every factual claim, including hedged or approximate ones, is supported by the provided policy excerpt. A claim with no support in the excerpt is a failure even if it is phrased as 'usually' or 'typically'." That is longer, and it is also the kind of specificity that a judge follows reliably. Most disagreements resolve this way: a term the writer thought was clear ("complete", "relevant", "addresses the question") turns out to have two readings, and the fix is to write down which reading you mean, with an example if the concept is slippery.
Some disagreements are the human's fault. A person labelling 50 rows at the end of the afternoon will misread a few, and when the judge's reasoning line makes a point the labeller missed, the label should change rather than the rubric. Record these separately from the rubric fixes, because they tell you something about how reliable your human labels are, and human labels are the ground your whole calibration stands on. If more than a handful of the ten are labelling errors, the labelling instructions need the same treatment as the rubric.
After the second round, what remains is a short list of rows where the judge and the human still disagree and you can explain why. Those rows are worth keeping as a permanent part of the test plan, because they mark the edge of what this judge can be trusted on. When a future model change pushes a lot of traffic into that edge, you want to know the score is on shaky ground there.
How to set a threshold
Teams spend a long time arguing about whether the threshold should be 0.7 or 0.75, as though there were a correct answer hiding in the data. There is not. The threshold encodes how much you would rather ship a bad answer than block a good release, and that trade is owned by whoever answers for the product, not by whoever wrote the metric. A team shipping a medical triage assistant and a team shipping a recipe suggester should hold the same judge to different thresholds, and neither number is more statistically correct than the other.
What the data can tell you is the cost of each choice. Sort your calibration rows by judge score and read the band around your candidate threshold. If moving from 0.70 to 0.75 turns four passes into failures and three of those four really were bad, you have learned something: the band between 0.70 and 0.75 mostly contains rows that deserve to fail, and the higher threshold is catching them. If it turns forty into failures, your judge is not discriminating in that range and no threshold there will hold. A judge whose scores bunch tightly around one value is telling you the rubric does not separate good from bad on the dimension you care about, and the cure is a better rubric, not a more precise threshold.
For binary judges the threshold sits on the run mean rather than on individual rows, and the same reading applies. Suppose your baseline sits at 0.82 with a calibrated false-pass rate near one in ten. A release that scores 0.80 is within the noise of the judge and the sample, and gating on a fixed 0.81 will block it for no reason. The useful question is not "is 0.80 below the line" but "is 0.80 to 0.82 a difference the judge can even see at this sample size". Running the same release through the judge two or three times, or comparing on a few hundred rows rather than 50, will tell you how much the score wobbles when nothing changes, and the threshold should sit outside that wobble.
Common failure modes
Three biases turn up in nearly every judge we have calibrated, and each one moves the score in a way that has nothing to do with the product. They are worth knowing by name because each has a check that takes minutes once you know to run it. The table shows the three side by side; the paragraphs below say why each one happens.
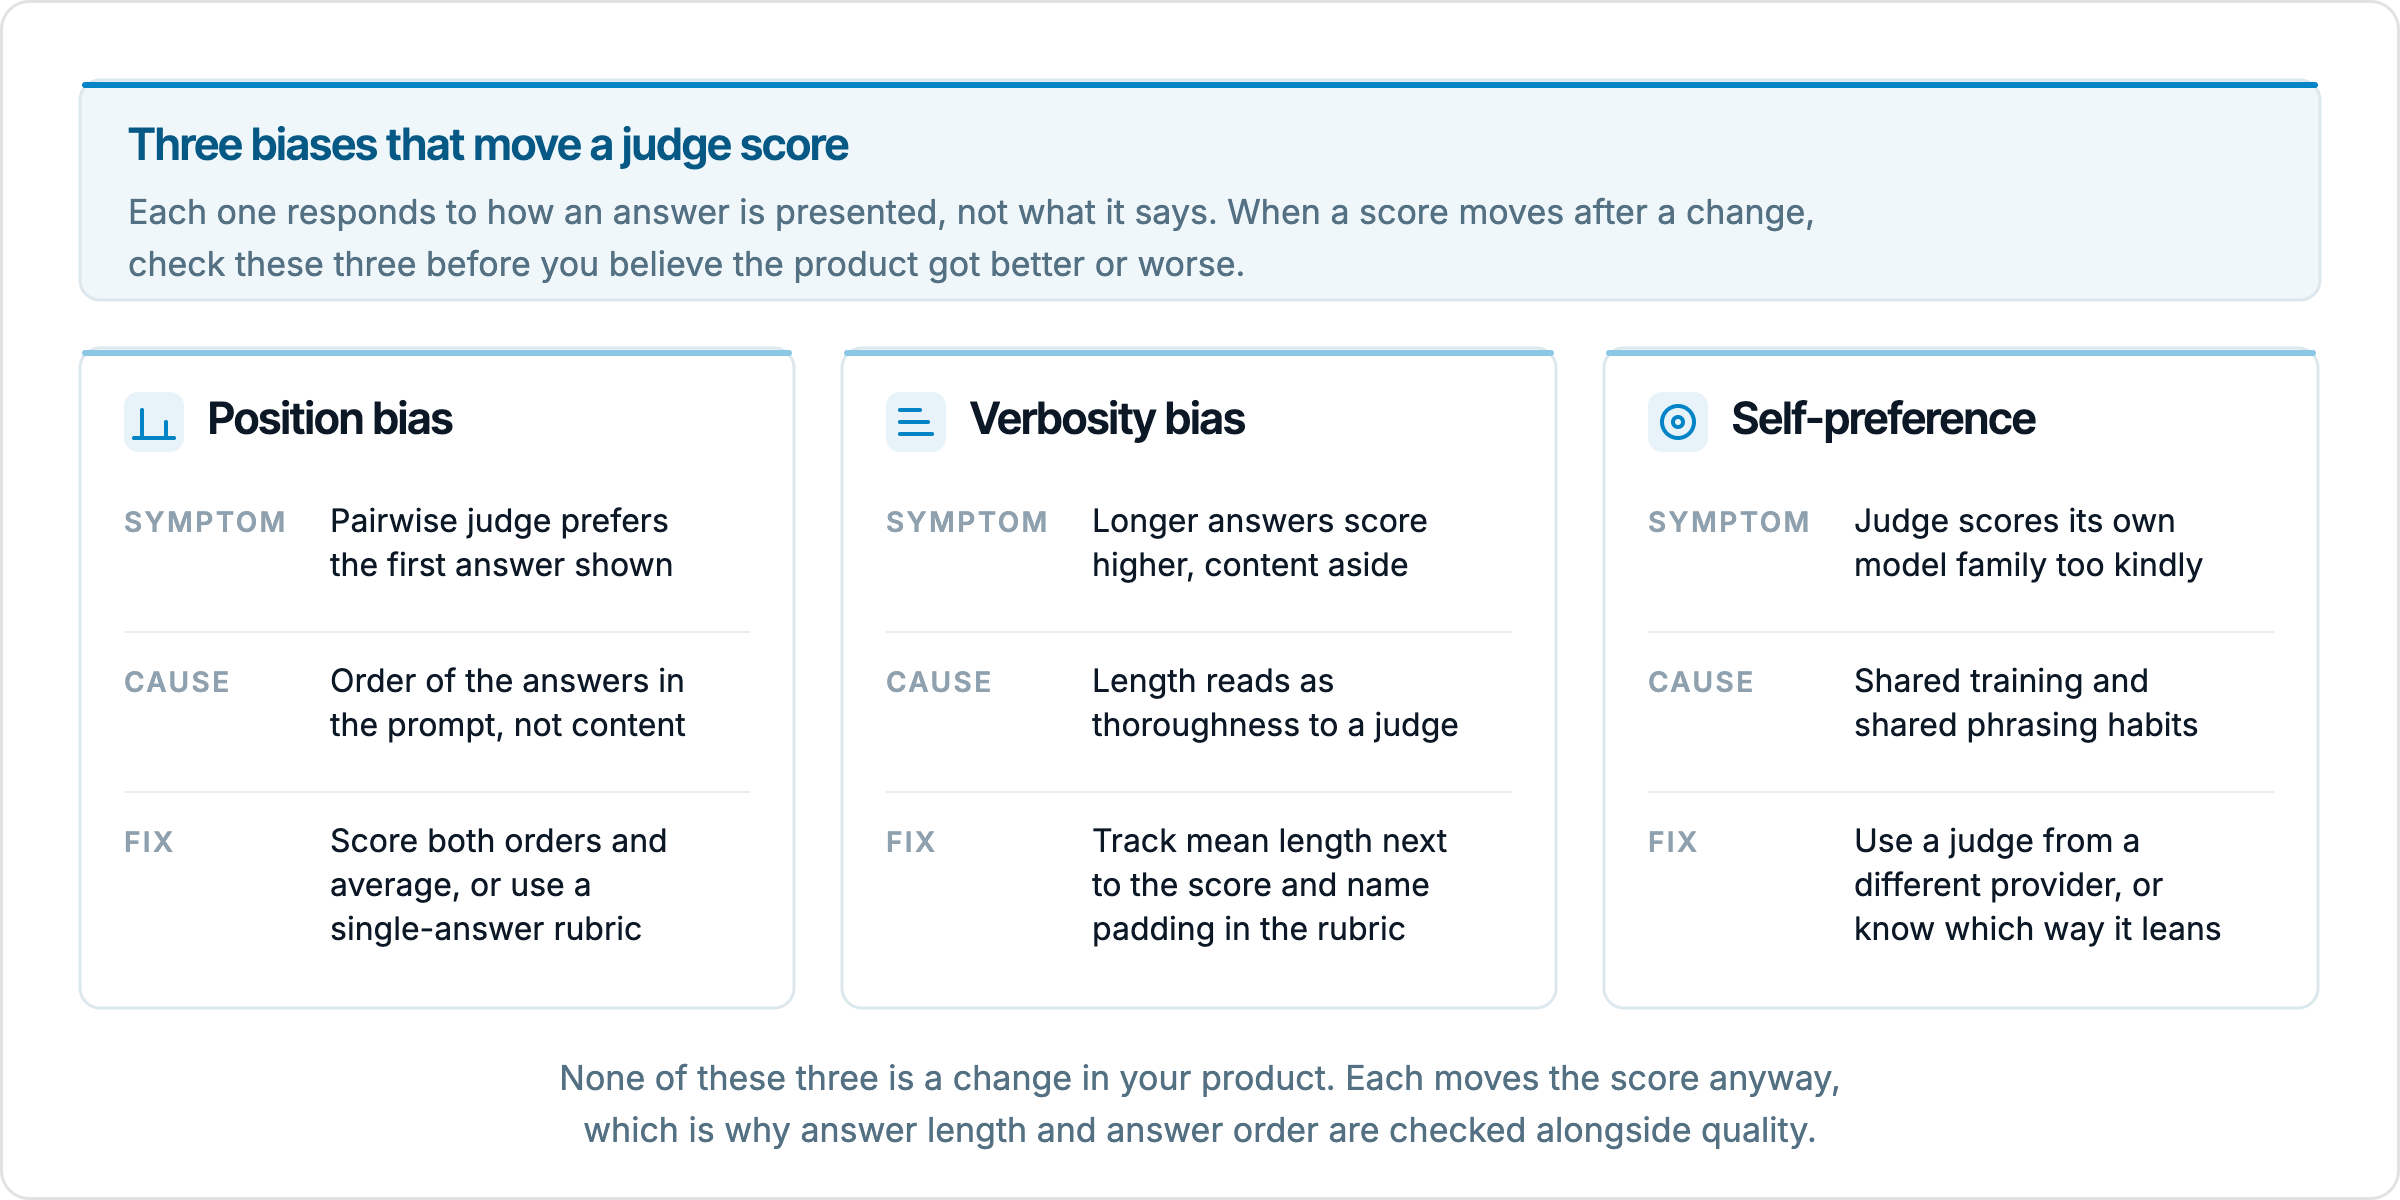
Position bias. Ask a judge to pick the better of two answers and it prefers the first one more often than chance. The order of two blocks of text in a prompt is not information about their quality, but the model treats it as if it were. Always score both orders and average, or use a single-answer rubric where each output is graded on its own. If you are running pairwise comparisons and have never swapped the order, the preference rate you have is partly an artifact of where you put the candidates.
Verbosity bias. Longer answers score higher, roughly regardless of content. Length reads as thoroughness to a judge in the same way it reads as effort to a tired reviewer. If your change made answers longer, expect a lift that is not real, and expect it to be largest on rubrics with words like "complete" or "thorough" in them. Check length alongside quality, always. A run whose score rose 3 points while mean answer length rose 40% has not been shown to be better; it has been shown to be longer.
Self-preference. A judge from the same family as the system under test scores it more kindly. The two share training data and phrasing habits, and the judge reads familiar phrasing as good phrasing. Use a different provider for the judge where you can, and at minimum know which way the bias points. When you cannot change the judge, the calibration matrix is your correction: if the judge is lenient towards its own family, the false-pass count will show it, and you can set the threshold higher to compensate.
Position and verbosity bias share a shape: the judge is responding to a feature of the presentation rather than a feature of the content. That is the general form of every judge failure mode. Whenever a score moves after a change, the first question is whether the change altered the content of the answers or only how they look to the judge, and the checks above are how you tell the two apart.
What calibration does not catch
A calibrated judge is a judge whose agreement with a human is known on 50 rows drawn from the traffic you had that afternoon. It is not a guarantee about traffic you did not sample. If a new intent arrives next month that none of the 50 rows resembled, the judge's agreement rate on it is unknown, and it will report 0.82 with the same confidence it always has. This is the coverage problem, and the only answer to it is to relabel a fresh sample periodically, especially after the input distribution shifts. Fifty rows also cannot show you a failure that happens 2% of the time, because the expected count in the sample is one row. Rare, serious failures need a targeted set built for them, not a random sample.
Calibration also cannot tell you the rubric asks the right question. A support judge calibrated to agree with humans nine times in ten on policy grounding will still pass an answer that is perfectly grounded, on topic, and useless, because "useless" is not among its conditions. The rubric defines the metric's blind spot, and no amount of agreement inside the rubric widens its field of view. When a score is high and users are unhappy, the rubric is the first thing to reread.
Two further limits are easy to forget. The first is that the human labels are themselves a sample from a person on a given afternoon, and two labellers will disagree on some rows; if you have never measured inter-labeller agreement, your calibration ceiling is unknown. The second is that hosted judge models change. A provider can update the model behind an identifier, and the judge you calibrated in March is not quite the judge you are running in June. Pinning a dated model version where the provider allows it, and rerunning the 50 rows when the version changes, is the only protection.
None of this makes the judge score useless. It makes it a measurement with a known scope, which is what every measurement is. The score answers one rubric's question, on traffic like the traffic it was checked on, with an agreement rate you have written down. Inside that scope it is a reliable way to compare Tuesday to Thursday. Outside it, it is a number, and you should say so in the slide.
Next steps
Pick the one metric that is currently in a slide. Find its rubric text and its judge model, and if either of those is not written down anywhere, that is the first fix. Then label 50 rows against it. You will find out in an afternoon whether the number in that slide means what the room thinks it means, and that is a cheaper way to find out than the alternative.
Once the confusion matrix exists, change the label on the slide. "Answer quality 0.82" becomes "policy-grounded and on-topic 0.82, judge v2, false-pass rate 4 in 50", or whatever your matrix says. The number has not changed, but now it carries its own caveats, and the next person to read it will ask the right question. From there, add the length check next to the score, swap the answer order once if you run pairwise comparisons, and put the rubric version on the chart so the next rubric edit starts a new line instead of drawing a regression that never happened.